LLM from scratch, to the aha moment, to a coding agent
Fifteen experiments on four RTX 4090s: one variable at a time, predictions written before each run, reconciled after.
Code: github.com/bethehand/lab1-llm-scratch-to-aha-moment-to-coding-agent
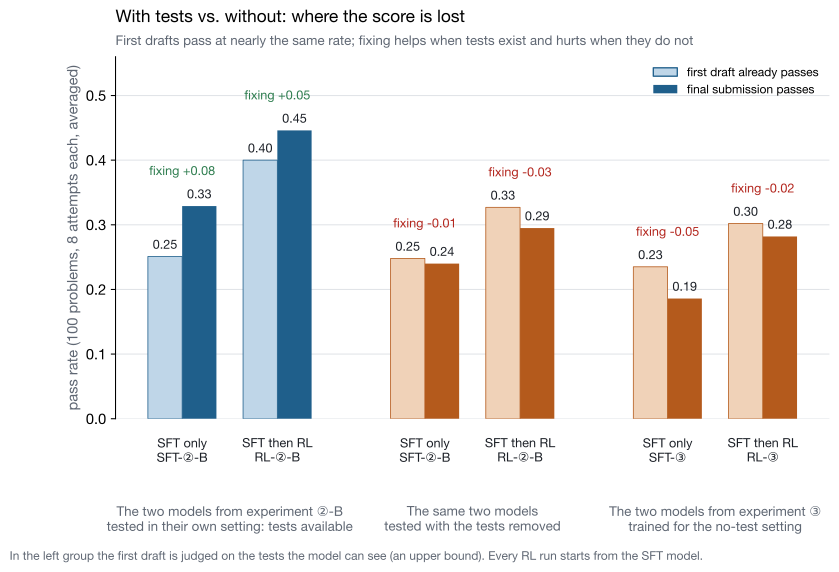
The price of observation. Same models, same hidden tests; only the visible tests are taken away at deployment. The RL-trained coding agent loses 16 points, all of it in the fix loop after the first draft. · 观测的价格。 同一批模型、同一套隐藏测试,部署时只拿走可见测试:RL 训出的编程 agent 掉 16 个点,全掉在第一稿之后的改稿循环里。
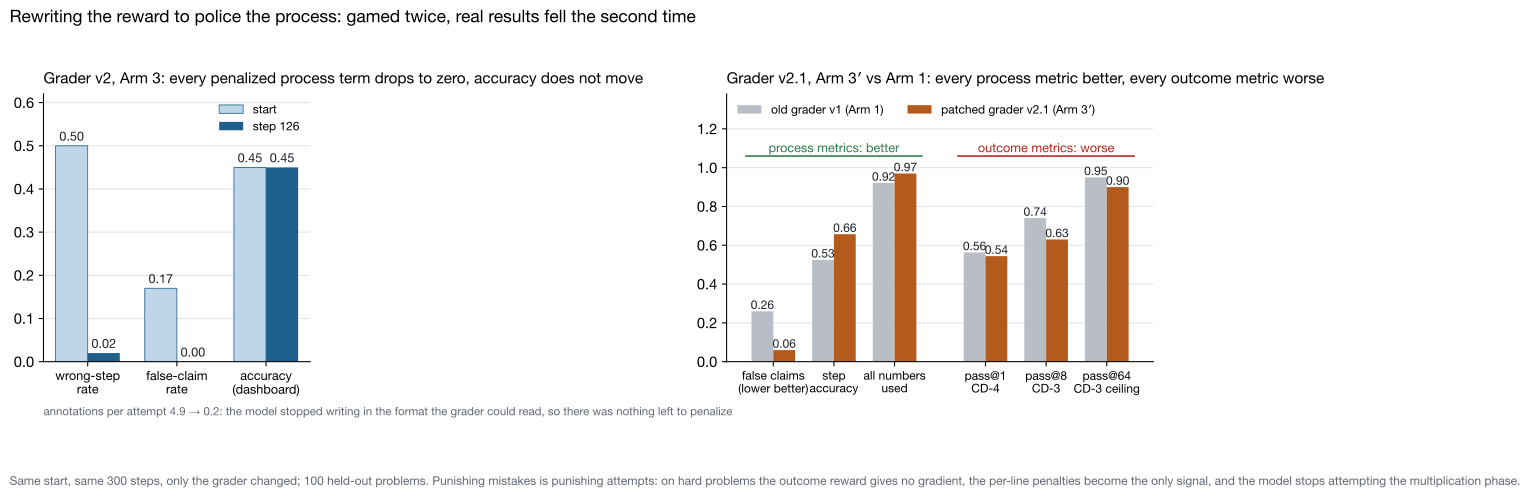
Rewriting the reward to police the process. Two attempts, both gamed: the first zeroed every penalty by changing its output format while accuracy stayed flat; the second made every process metric better and every real result worse. Punishing mistakes is punishing attempts. · 改奖励公式去管过程。 两次都被钻:第一次换个写法让罚项全归零、正确率没动;第二次过程指标全好、真实成绩全差。罚错误等于罚尝试。
Run it yourself: bench_observation_price.py measures the price of observation on any Hugging Face model; make smoke walks the environments, harness and graders on a laptop with no GPU. · 自己跑一遍:bench_observation_price.py 在任何 Hugging Face 模型上量观测的价格;make smoke 在没有 GPU 的笔记本上走一遍环境、harness 和秤。
Pretrain two English models from scratch (95M, 201M), SFT, then reinforcement learning: reproduce GRPO on GSM8K, chase DeepSeek-R1’s “aha moment” on the Countdown game and lift its pass@1 from 0.02 to 0.75 (0.98 with an expert on call), build the first stateful environment (number guessing), then a four-stage coding-agent curriculum: fix bugs, bundle bugs, write real modules from scratch, and finally remove the tests so the model must verify itself. Six regularities fall out, each with its own numbers: RL reweights inside the support set; pretraining gives the parts, SFT the procedure, RL the preference; the shape of the reward decides what gets learned; the price of observation; fixing is a part, not a habit; path-opening = support density × feedback density × sampling budget.
从零预训练两个英文模型(95M、201M),做 SFT,再转到 RL:在 GSM8K 上复现 GRPO,用 Countdown 追 DeepSeek-R1 的「顿悟」并把 pass@1 从 0.02 抬到 0.75(开专家出口 0.98),做第一个有状态的环境(猜数字),最后进入四级编程 agent 课程:修 bug、拼包、从头写真实模块、拿走测试让模型自己验证。六条规律各有自己的数。